Method and sources
Base text. The Ḥafṣ text is the Tanzil Project Uthmani text, shown exactly as published (Creative Commons Attribution 3.0; tanzil.net ). Nothing in it is changed; differing words are only highlighted.
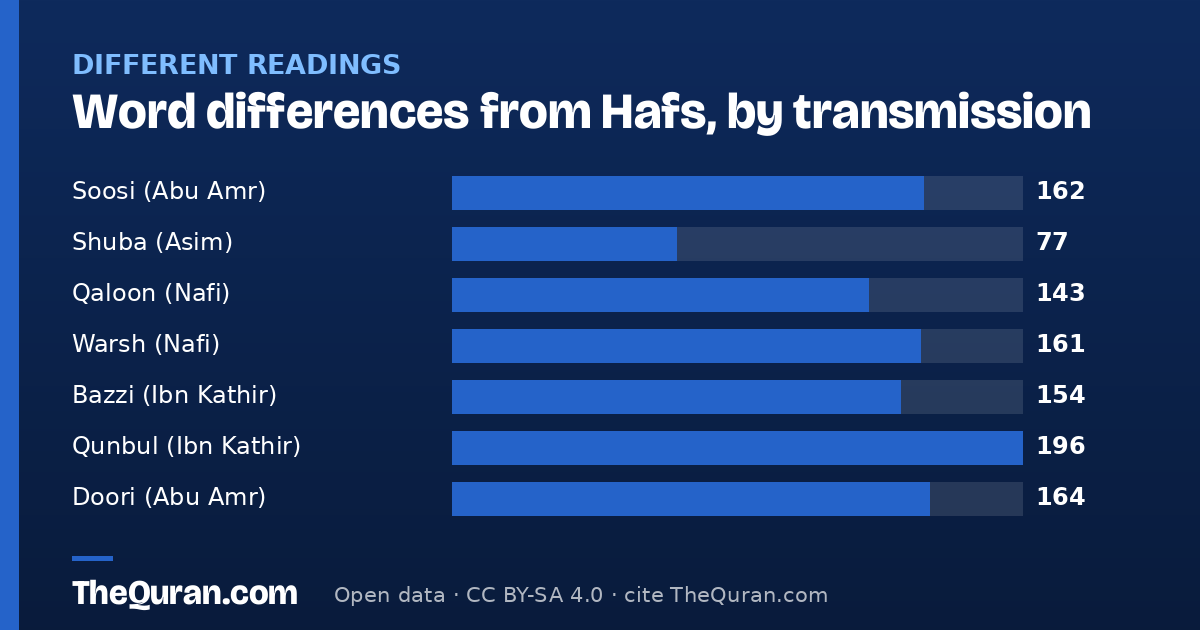
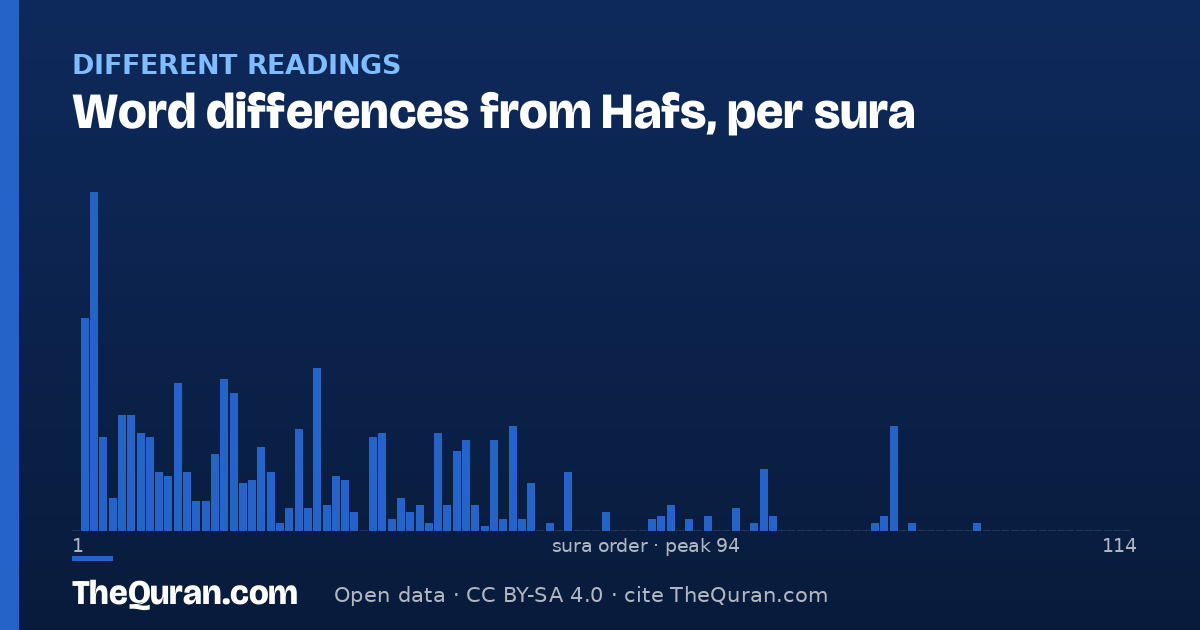
Differences. At every variant spot in the Quranpedia qiraat dataset (quranpedia.net ), the reading of each of Shuʿba, Qālūn, Warsh, al-Bazzī, Qunbul, al-Dūrī and al-Sūsī that Ḥafṣ does not share is compared with Ḥafṣ word by word, after removing vowel signs, Qur'anic marks and alef spellings and folding hamza seats. A word whose letters or dots differ is listed, placed on the Tanzil word it replaces. Readings that differ only in vowels, or only in connected-speech features (assimilation, softened hamza, linking vowels), are not listed here; they are in the recorded readings. Each row cites the Quranpedia spot, and is checked against the Corpus Coranicum variant database (BBAW, CC BY-SA 4.0): 1,041 of 1,057 are attested there for the same transmitter or his reader. The forms shown for other transmissions are short word quotations, not running text.
Review. The set replaces an earlier one computed from King Fahd Complex electronic texts, which this site no longer uses. 676 of those 757 differences are matched exactly, 37 closely; 26 have no support yet and are not shown until a reviewer checks them against al-Dānī's al-Taysīr and Ibn al-Jazarī's al-Nashr ; 18 spelling-only items were dropped. Code: tools/build_reading_differences.py; reviewer list: docs/readings-reconciliation.csv.